With the amount of new subnets being added it can be hard to get up to date information across all subnets, so data may be slightly out of date from time to time
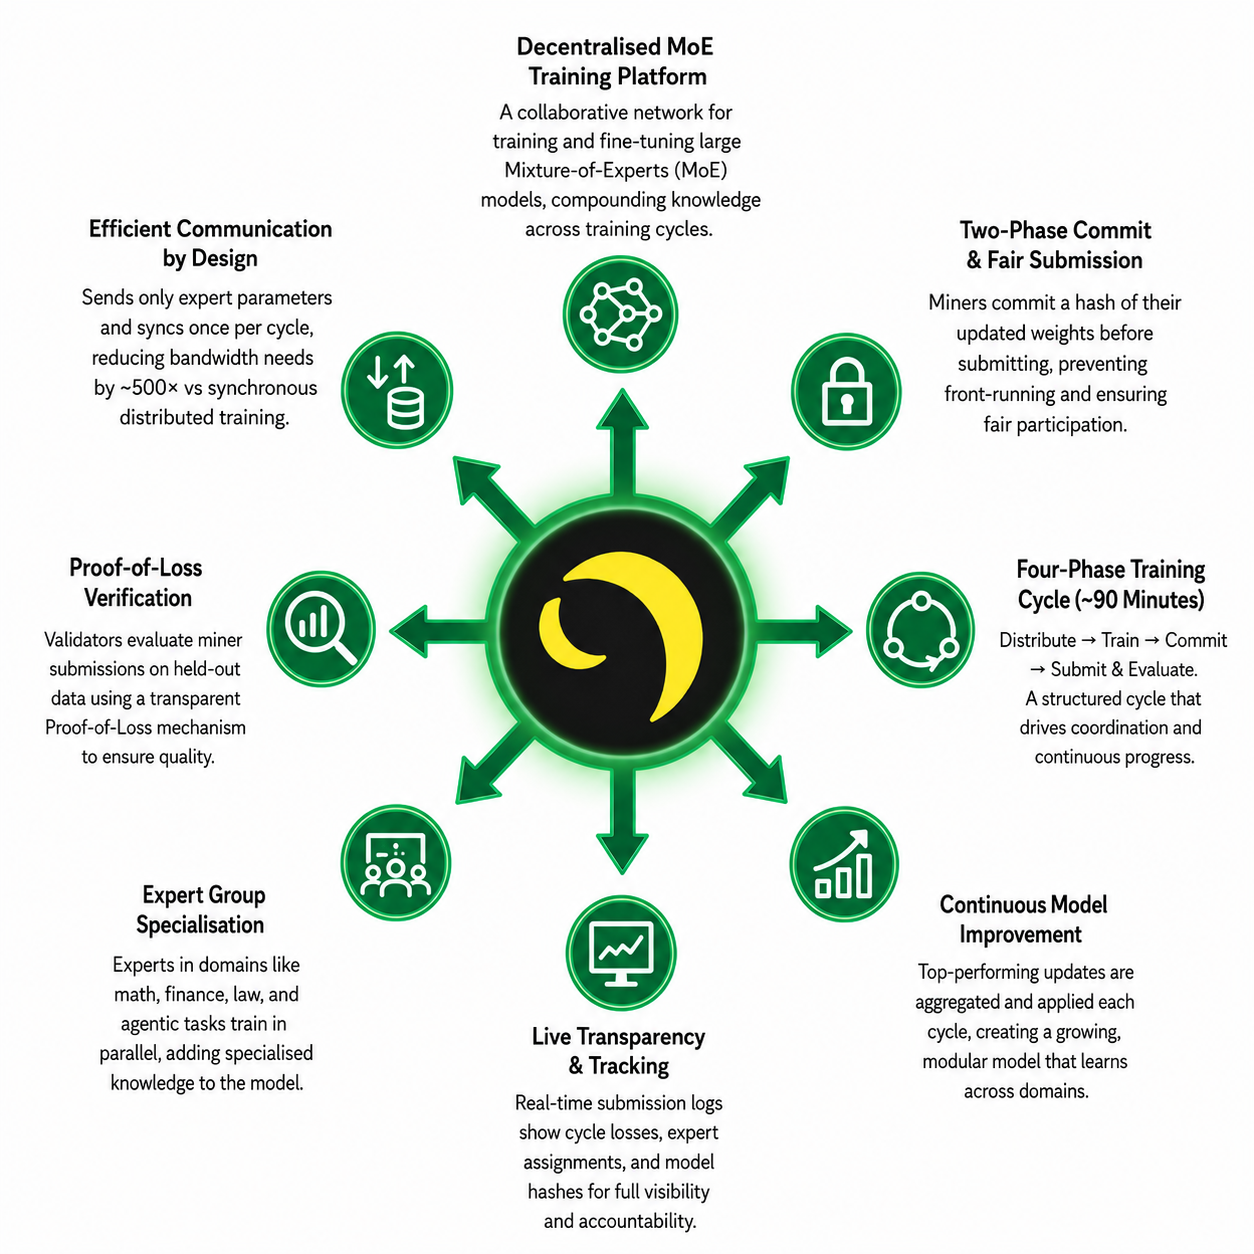
ConnitoAI is Bittensor Subnet 102 — a decentralised, collaborative platform for training and fine-tuning large Mixture-of-Experts (MoE) language models. Rather than requiring every participant to host or train an entire 100-billion-plus parameter model, the network partitions the model into specialised “experts” — small, task-focused submodules — and assigns each expert group to independent miners. Validators coordinate training cycles, evaluate miner submissions via a transparent Proof-of-Loss mechanism on held-out data, and aggregate only the top-performing updates into the shared global model. The result is a continuously improving, modular AI system that compounds knowledge across each training cycle.
The subnet operates on a four-phase cycle lasting approximately 90 minutes (450 Bittensor blocks). In the Distribute phase, validators serve only the specific expert weights that each assigned miner requires. In the Train phase, miners perform around 100 local gradient steps using AdamW with a cosine learning-rate schedule on their domain dataset. During Commit, miners post a cryptographic hash of their updated weights before submitting them — a two-phase commit that prevents front-running. Finally, in Submit & Evaluate, validators compute Proof-of-Loss scores for each miner’s submission, average the top-performing updates using a DiLoCo-style outer optimiser (Nesterov SGD), and call set_weights() on-chain to distribute TAO emission rewards proportionally to contribution quality.
Communication efficiency is a core design principle. By transmitting only sparse expert parameters — rather than the full model — and synchronising just once per cycle rather than at every gradient step, ConnitoAI reduces inter-node bandwidth requirements by approximately 500× compared to synchronous distributed training approaches. This makes meaningful participation accessible to miners without hyperscaler-grade infrastructure, opening expert-level model training to a genuinely decentralised network.
Expert groups currently active on the subnet include domains such as mathematics, finance, law, and agentic tasks. Each cycle contributes new expert knowledge that is folded into the growing shared model, enabling a form of cross-domain “neuroplasticity” in which improvements in one domain can reinforce capabilities across the wider system. The live submission log on the ConnitoAI website displays recent cycle losses, expert group assignments, and model hashes in real time.
ConnitoAI is Bittensor Subnet 102 — a decentralised, collaborative platform for training and fine-tuning large Mixture-of-Experts (MoE) language models. Rather than requiring every participant to host or train an entire 100-billion-plus parameter model, the network partitions the model into specialised “experts” — small, task-focused submodules — and assigns each expert group to independent miners. Validators coordinate training cycles, evaluate miner submissions via a transparent Proof-of-Loss mechanism on held-out data, and aggregate only the top-performing updates into the shared global model. The result is a continuously improving, modular AI system that compounds knowledge across each training cycle.
The subnet operates on a four-phase cycle lasting approximately 90 minutes (450 Bittensor blocks). In the Distribute phase, validators serve only the specific expert weights that each assigned miner requires. In the Train phase, miners perform around 100 local gradient steps using AdamW with a cosine learning-rate schedule on their domain dataset. During Commit, miners post a cryptographic hash of their updated weights before submitting them — a two-phase commit that prevents front-running. Finally, in Submit & Evaluate, validators compute Proof-of-Loss scores for each miner’s submission, average the top-performing updates using a DiLoCo-style outer optimiser (Nesterov SGD), and call set_weights() on-chain to distribute TAO emission rewards proportionally to contribution quality.
Communication efficiency is a core design principle. By transmitting only sparse expert parameters — rather than the full model — and synchronising just once per cycle rather than at every gradient step, ConnitoAI reduces inter-node bandwidth requirements by approximately 500× compared to synchronous distributed training approaches. This makes meaningful participation accessible to miners without hyperscaler-grade infrastructure, opening expert-level model training to a genuinely decentralised network.
Expert groups currently active on the subnet include domains such as mathematics, finance, law, and agentic tasks. Each cycle contributes new expert knowledge that is folded into the growing shared model, enabling a form of cross-domain “neuroplasticity” in which improvements in one domain can reinforce capabilities across the wider system. The live submission log on the ConnitoAI website displays recent cycle losses, expert group assignments, and model hashes in real time.
ConnitoAI is positioning itself as a next-generation Training-as-a-Service (TaaS) offering for organisations that need custom LLM fine-tuning at scale. Enterprises define domain-specific tasks and supply their own training data; ConnitoAI orchestrates a decentralised pool of competing miners who deliver the best possible expert updates. The model competes with traditional fine-tuning consultancies on cost and with self-serve API providers on depth and specialisation, occupying a distinct market position between the two.
The primary target customers are enterprise AI teams with recurring, heavy fine-tuning needs — legal technology firms, financial services providers, and research organisations that require continuously improving domain-specific models rather than static snapshots. GPU-rich participants on Bittensor can earn TAO rewards by hosting expert training tasks, making the supply side of the marketplace self-sustaining through aligned incentives. The Proof-of-Loss scoring system ensures that miners are only rewarded for genuine, measurable quality improvements, preventing the low-quality submission problem that plagues many open contribution networks.
The technical stack is built primarily in Python and Jupyter Notebook, with Docker support for reproducible miner and validator environments. The GitHub repository (github.com/Connito-AI/Connito) contains over 572 commits, covering the core training loop, expert group management, observability tooling, DHT-based phase service, and CI/CD workflows. The April 2026 “Checkpoint transport update” release added improved checkpoint handling via HTTP Range requests, enabling more efficient distribution of large expert weight files across geographically distributed validators and miners.
Looking at the longer product roadmap, ConnitoAI plans to launch a customer-facing training platform and, ultimately, a model marketplace and customisation centre where organisations can browse, select, and deploy pre-trained expert modules for their specific vertical. Each accepted expert submission becomes a permanent, reusable component of a growing expert library, meaning the value of early contributions compounds over time. This “modular models as product architecture” approach — described in the team’s June 2026 blog post — treats expert modules as durable intellectual assets rather than throwaway fine-tuning artefacts.
ConnitoAI is positioning itself as a next-generation Training-as-a-Service (TaaS) offering for organisations that need custom LLM fine-tuning at scale. Enterprises define domain-specific tasks and supply their own training data; ConnitoAI orchestrates a decentralised pool of competing miners who deliver the best possible expert updates. The model competes with traditional fine-tuning consultancies on cost and with self-serve API providers on depth and specialisation, occupying a distinct market position between the two.
The primary target customers are enterprise AI teams with recurring, heavy fine-tuning needs — legal technology firms, financial services providers, and research organisations that require continuously improving domain-specific models rather than static snapshots. GPU-rich participants on Bittensor can earn TAO rewards by hosting expert training tasks, making the supply side of the marketplace self-sustaining through aligned incentives. The Proof-of-Loss scoring system ensures that miners are only rewarded for genuine, measurable quality improvements, preventing the low-quality submission problem that plagues many open contribution networks.
The technical stack is built primarily in Python and Jupyter Notebook, with Docker support for reproducible miner and validator environments. The GitHub repository (github.com/Connito-AI/Connito) contains over 572 commits, covering the core training loop, expert group management, observability tooling, DHT-based phase service, and CI/CD workflows. The April 2026 “Checkpoint transport update” release added improved checkpoint handling via HTTP Range requests, enabling more efficient distribution of large expert weight files across geographically distributed validators and miners.
Looking at the longer product roadmap, ConnitoAI plans to launch a customer-facing training platform and, ultimately, a model marketplace and customisation centre where organisations can browse, select, and deploy pre-trained expert modules for their specific vertical. Each accepted expert submission becomes a permanent, reusable component of a growing expert library, meaning the value of early contributions compounds over time. This “modular models as product architecture” approach — described in the team’s June 2026 blog post — treats expert modules as durable intellectual assets rather than throwaway fine-tuning artefacts.
ConnitoAI was founded by Isabella Liu ([email protected]) and George Kim ([email protected]), who are listed as the primary authors of the official ConnitoAI whitepaper. Isabella Liu has a background in machine learning software engineering, with prior involvement at the OpenTensor Foundation (the core development organisation behind the Bittensor protocol) and academic research experience at HKUST. George Kim’s background has not been publicly detailed beyond his co-authorship role on the project’s technical documentation.
The team maintains an active engineering presence through the GitHub repository, which shows consistent commit activity across core training infrastructure, expert group management, distributed systems code, and observability tooling. Community engagement takes place via the ConnitoAI Discord server and the project’s blog, where the team publishes technical deep-dives on topics including subnet performance reviews, modular model architecture, and the philosophy of composable intelligence. As of mid-2026, the core team appears to be small and technically focused, with public communications centred on documentation and code rather than marketing.
The project was formally registered on the Bittensor mainnet as Subnet 102 in March 2026, with an alpha code release announced in Q4 2025. The whitepaper, architecture documentation, and a growing body of blog content demonstrate a team with deep familiarity with both the Bittensor protocol internals and the practical challenges of distributed model training at scale.
ConnitoAI was founded by Isabella Liu ([email protected]) and George Kim ([email protected]), who are listed as the primary authors of the official ConnitoAI whitepaper. Isabella Liu has a background in machine learning software engineering, with prior involvement at the OpenTensor Foundation (the core development organisation behind the Bittensor protocol) and academic research experience at HKUST. George Kim’s background has not been publicly detailed beyond his co-authorship role on the project’s technical documentation.
The team maintains an active engineering presence through the GitHub repository, which shows consistent commit activity across core training infrastructure, expert group management, distributed systems code, and observability tooling. Community engagement takes place via the ConnitoAI Discord server and the project’s blog, where the team publishes technical deep-dives on topics including subnet performance reviews, modular model architecture, and the philosophy of composable intelligence. As of mid-2026, the core team appears to be small and technically focused, with public communications centred on documentation and code rather than marketing.
The project was formally registered on the Bittensor mainnet as Subnet 102 in March 2026, with an alpha code release announced in Q4 2025. The whitepaper, architecture documentation, and a growing body of blog content demonstrate a team with deep familiarity with both the Bittensor protocol internals and the practical challenges of distributed model training at scale.
The ConnitoAI public roadmap, outlined on the project homepage, spans six progressive milestones. The first two phases focus on proving the core incentive mechanism works reliably and demonstrating proof points in high-value domains — specifically mathematics and legal reasoning — where output quality is objectively measurable. Phases three and four introduce a bi-weekly operating cadence: alternating weeks dedicated to integrating new expert specialisations and running structured benchmarks, respectively, alongside multi-expert system testing to validate composability across domains.
The final two phases represent the commercial expansion of the platform: a customer-facing training platform that allows enterprises to commission custom expert training directly, followed by a full model marketplace and customisation centre where clients can browse, select, and deploy pre-trained expert modules. The team’s blog posts from June and August 2026 provide additional colour on the long-term architectural vision — specifically the concept of treating expert modules as composable, reusable intellectual assets that accumulate value with each training cycle, eventually forming a self-reinforcing library of specialised AI capability.
The ConnitoAI whitepaper’s “Future Outlook” section also describes planned work on expert lifecycle management (retiring stale experts, versioning updates), routing enhancements to improve how the global MoE selects experts at inference time, and deeper integration with the broader Bittensor ecosystem as the subnet matures.
The ConnitoAI public roadmap, outlined on the project homepage, spans six progressive milestones. The first two phases focus on proving the core incentive mechanism works reliably and demonstrating proof points in high-value domains — specifically mathematics and legal reasoning — where output quality is objectively measurable. Phases three and four introduce a bi-weekly operating cadence: alternating weeks dedicated to integrating new expert specialisations and running structured benchmarks, respectively, alongside multi-expert system testing to validate composability across domains.
The final two phases represent the commercial expansion of the platform: a customer-facing training platform that allows enterprises to commission custom expert training directly, followed by a full model marketplace and customisation centre where clients can browse, select, and deploy pre-trained expert modules. The team’s blog posts from June and August 2026 provide additional colour on the long-term architectural vision — specifically the concept of treating expert modules as composable, reusable intellectual assets that accumulate value with each training cycle, eventually forming a self-reinforcing library of specialised AI capability.
The ConnitoAI whitepaper’s “Future Outlook” section also describes planned work on expert lifecycle management (retiring stale experts, versioning updates), routing enhancements to improve how the global MoE selects experts at inference time, and deeper integration with the broader Bittensor ecosystem as the subnet matures.
Connito AI Follow 23 703
Building Specialised AI on Decentralized infrastructure in @bittensor SN102
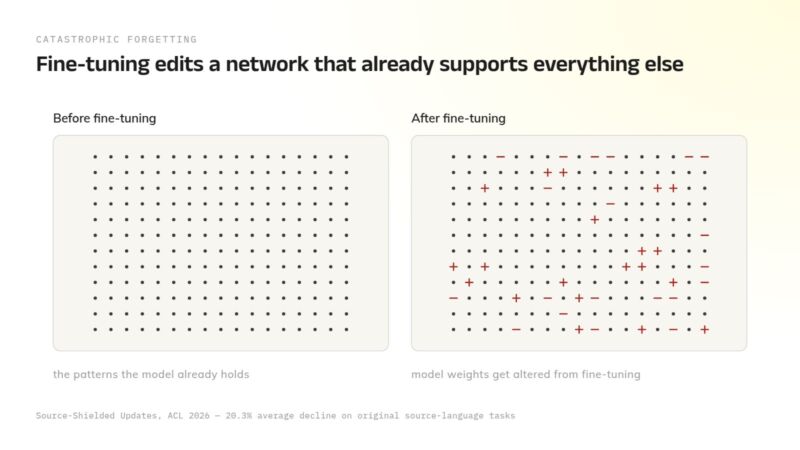
Yes, forgetting happens when you teach a model new things.
But forgetting dose not just happen even through out the model. Research says that it happens particularly in the router.
To become an insider for how LLM works:

Finetuning Instead of Expensive Frontier Models
Finetuning gives you opportunity to build smaller and more efficient models that can fit into your at home GPU.
Buttt at the cost possibly forgetting old knowledge.
Check out this explanatory post of how do models learn new
Finetuning Instead of Expensive Frontier Models
Finetuning gives you opportunity to build smaller and more efficient models that can fit into your at home GPU.
Buttt at the cost possibly forgetting old knowledge.
Check out this explanatory post of how do models learn new
Building Modular Intelligence
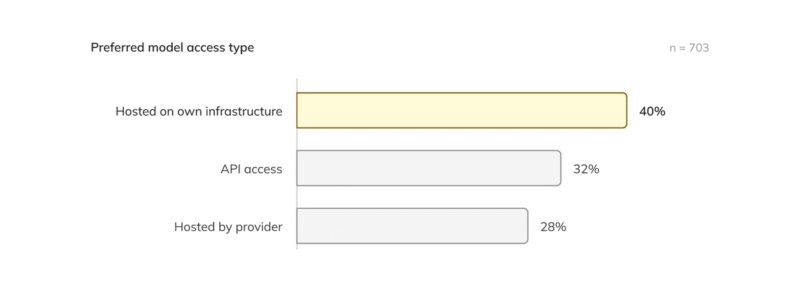
Would you prefer hosting AI model on your own infrastructure or use direct API access?
McKinsey's report Open source technology in the age of AI indicate that most prefer the first.
How is it the case? And how can Connito make it easier for
Building Modular Intelligence
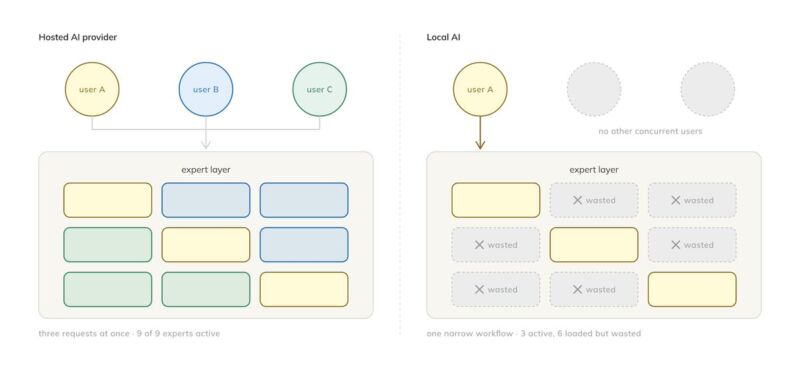
Ever wondered how can model inference be cheap for providers, but expensive when you try to run it locally? The answer could be architectural due to model parts utilization.
Check out what Connito offers to make this effort smooth for you.
Read
--- Building Modular Intelligence Series ---
What if the future of AI isn’t one model that knows everything?
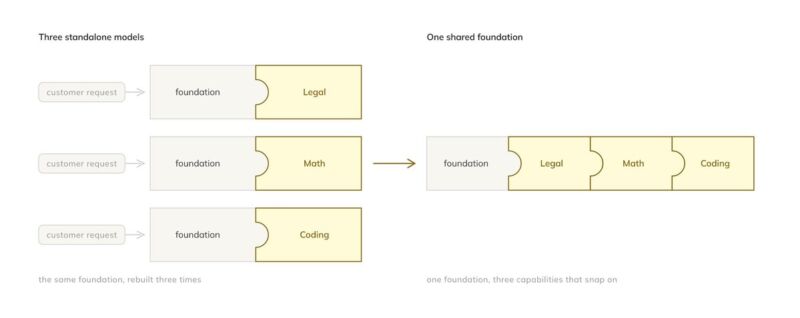
For many tasks, we don’t need every capability a giant model carries. We need the right capability, at the right level of performance, without paying for everything
Excited the see the @bittensor community at the @ExploitSummit
Sept 28-29th, 2026
Montreal, Canada